Qwen3.8-27B on one RTX 5090: 376 tok/s total at 32 chats, measured llama.cpp throughput sweep
Published 2026-11-16
This is a stock llama.cpp Q4_K_M comparison point on one RTX 5090. It is not a reproduction of anyone else's demo. It answers one question: how does total output grow as more chats share one card, and where does memory run out as the prompt gets longer? For the single-chat yardstick and why headline tok/s claims differ, see headline vs single-chat tok/s.
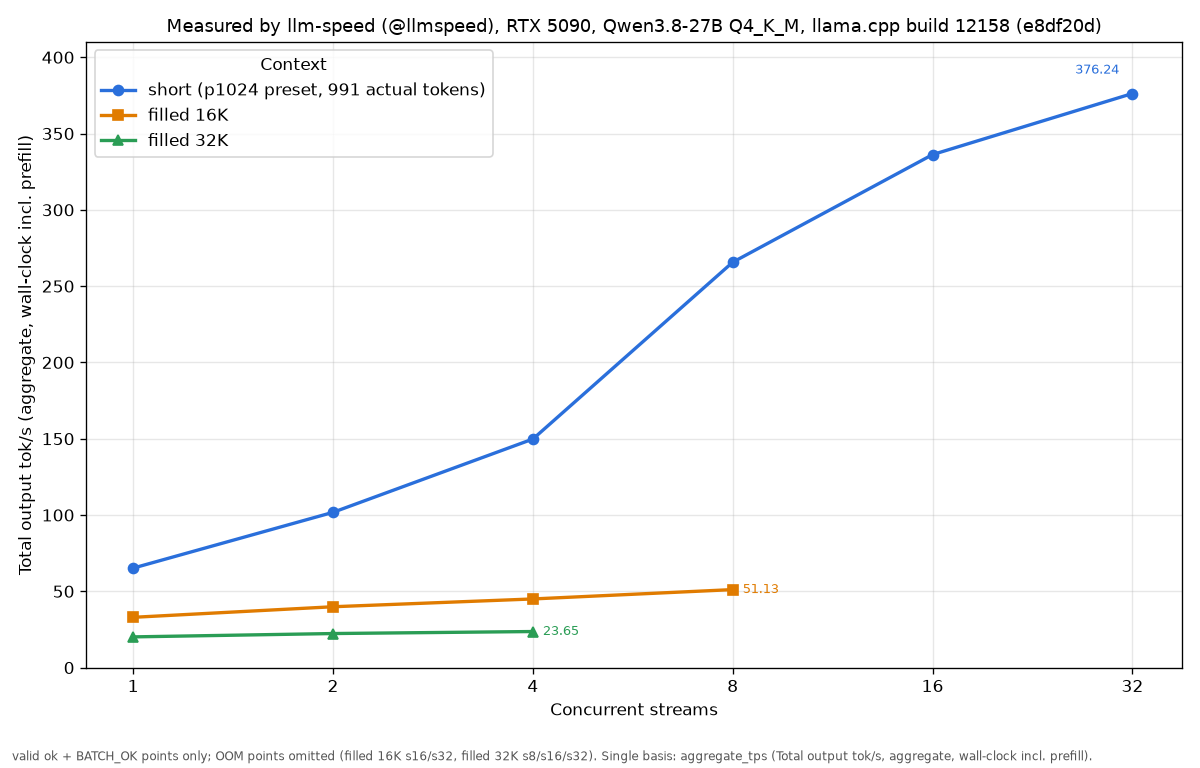
aggregate_tps), one basis only. One line per context; only publishable points (valid ok with a matching BATCH_OK) are drawn, and the OOM points (filled 16K at 16 and 32 streams, filled 32K at 8, 16 and 32) are omitted. Per-stream decode is not on this chart.Setup
- Hardware: one RTX 5090 (32607 MiB VRAM reported).
- Engine: llama.cpp build 12158 (e8df20d), full commit
e8df20d238853b2f4fa460ad4c0757116a271400, unmodified. One llama-server per point, all layers on the GPU (-ngl 999,--fit off),--no-cache-prompt --cache-ram 0,--reasoning off,--temp 0 --seed 42,--parallelset to the stream count. - CLI: llm-speed 0.0.23.
- Model file:
Qwen3.8-27B-Q4_K_M.gguf, sha256c600de0300ae8a0eb3a6c0b8b5561b8b96f16bd2c863c2a66c42de29d391a747. - Workload: concurrent-decode, 256 output tokens per stream. Contexts: short = p1024 preset, 991 actual tokens; filled 16K (15,857 prompt tokens); filled 32K (32,241 prompt tokens). Streams: 1, 2, 4, 8, 16, 32.
- Finished 2026-11-12 14:32:07 Asia/Singapore (UTC+8). Session exit code 0.
Results by context and stream count
Attempts: 18. Publishable (valid ok with a matching BATCH_OK and finite metrics): 13. OOM (LOAD_FAIL): 5. Other invalid: 0. Attempt ids 6–9 do not exist by design.
| Context | Streams | Attempt | Status | Run | Per-stream decode tok/s (generation-only) | Total output tok/s (aggregate, wall-clock incl. prefill) | TTFT p50 ms | TTFT max ms | Prefill tok/s (1 stream only) | Peak VRAM MiB |
|---|---|---|---|---|---|---|---|---|---|---|
| short (p1024 preset, 991 actual tokens) | 1 | 0 | valid ok | r_iqcsaltiygj | 71.02 | 65.22 | 334.8 | 334.8 | 2981.36 (source: server_prompt_per_second) | 18400 |
| short (p1024 preset, 991 actual tokens) | 2 | 1 | valid ok | r_w1ghhizti-d | 58.18 | 101.77 | 639.38 | 673.64 | omitted (multi-stream; see TTFT) | 18630 |
| short (p1024 preset, 991 actual tokens) | 4 | 2 | valid ok | r_1xnjfp4smsq | 45.29 | 149.8 | 1229.66 | 1230.88 | omitted (multi-stream; see TTFT) | 19090 |
| short (p1024 preset, 991 actual tokens) | 8 | 3 | valid ok | r_gihyz5jfgc8 | 46.13 | 265.69 | 2246.29 | 2525.84 | omitted (multi-stream; see TTFT) | 20044 |
| short (p1024 preset, 991 actual tokens) | 16 | 4 | valid ok | r_4nge7d__8-x | 30.31 | 336.21 | 3548.06 | 5023.46 | omitted (multi-stream; see TTFT) | 21932 |
| short (p1024 preset, 991 actual tokens) | 32 | 5 | valid ok | r_i1r0ngxz4hh | 17.25 | 376.24 | 6193.38 | 10345.45 | omitted (multi-stream; see TTFT) | 25706 |
| filled 16K | 1 | 10 | valid ok | r_a9_1mrekhnd | 67.82 | 32.96 | 4007.18 | 4007.18 | 3974.69 (source: server_prompt_per_second) | 19342 |
| filled 16K | 2 | 11 | valid ok | r_3ogoh9fqwyn | 44.2 | 39.89 | 6651.99 | 8186.2 | omitted (multi-stream; see TTFT) | 20500 |
| filled 16K | 4 | 12 | valid ok | r_-93wbtb83mc | 25.79 | 45 | 11340.35 | 16634.12 | omitted (multi-stream; see TTFT) | 22818 |
| filled 16K | 8 | 13 | valid ok | r_hwqgx8_47vr | 17.48 | 51.13 | 19881.55 | 33745.77 | omitted (multi-stream; see TTFT) | 27450 |
| filled 16K | 16 | 14 | OOM (LOAD_FAIL) | — | not measured | not measured | not measured | not measured | not measured | not measured |
| filled 16K | 32 | 15 | OOM (LOAD_FAIL) | — | not measured | not measured | not measured | not measured | not measured | not measured |
| filled 32K | 1 | 16 | valid ok | r_vizpaqn9m8c | 64.96 | 20.14 | 8784.57 | 8784.57 | 3684.58 (source: server_prompt_per_second) | 20382 |
| filled 32K | 2 | 17 | valid ok | r_dzvdfwvwcbr | 35.81 | 22.33 | 13951.95 | 17990.1 | omitted (multi-stream; see TTFT) | 22564 |
| filled 32K | 4 | 18 | valid ok | r_7nl1vae_gek | 18.64 | 23.65 | 23720.81 | 36703.99 | omitted (multi-stream; see TTFT) | 26930 |
| filled 32K | 8 | 19 | OOM (LOAD_FAIL) | — | not measured | not measured | not measured | not measured | not measured | not measured |
| filled 32K | 16 | 20 | OOM (LOAD_FAIL) | — | not measured | not measured | not measured | not measured | not measured | not measured |
| filled 32K | 32 | 21 | OOM (LOAD_FAIL) | — | not measured | not measured | not measured | not measured | not measured | not measured |
Column notes
- Per-stream decode tok/s:
per_stream_tps, decode basisserver_timings(llama-server per-slot decode timing). Generation-only. - Total output tok/s (aggregate, wall-clock incl. prefill):
aggregate_tpsas recorded by llm-speed. It matches output tokens across all streams divided by the point's wall time, so it includes prompt processing. That is why it is below per-stream decode at 1 stream, and why it is much lower for the filled 16K and filled 32K contexts. - TTFT p50 / max:
ttft_ms(p50) andttft_max_msacross the point's streams. - Prefill tok/s is shown only at 1 stream and only when its source is
server_prompt_per_second(true for all 3 one-stream points). Multi-stream points show TTFT, not prefill tok/s. A TTFT-derived prefill is never labelled or charted as prefill. - Peak VRAM: the runner's
VRAM_PEAK_MIBis canonical and is the value used for fits. The public APIpeak_vram_mibdiffers by 2–6 MiB on 12 of the 13 uploaded points (CLI sampling vs runner sampling).
Total output tok/s (aggregate, wall-clock incl. prefill) grid
| Streams | short (p1024 preset, 991 actual tokens) | filled 16K | filled 32K |
|---|---|---|---|
| 1 | 65.22 | 32.96 | 20.14 |
| 2 | 101.77 | 39.89 | 22.33 |
| 4 | 149.8 | 45 | 23.65 |
| 8 | 265.69 | 51.13 | OOM |
| 16 | 336.21 | OOM | OOM |
| 32 | 376.24 | OOM | OOM |
What fits
The short context ran at every stream count up to 32 (peak 25706 MiB at 32 streams). Filled 16K fit up to 8 chats (27450 MiB peak) and filled 32K up to 4 chats (26930 MiB peak). Five points failed to allocate the model and KV cache (OOM, LOAD_FAIL) and have no numbers: filled 16K at 16 and 32 streams; filled 32K at 8, 16 and 32 streams.
Long prompts dominate the wall clock. At 1 stream, per-stream decode stays between 64.96 and 71.02 tok/s across the three contexts, but total output falls from 65.22 (short) to 32.96 (filled 16K) and 20.14 (filled 32K), because each point's wall time includes reading the prompt (TTFT p50 334.8 ms short, 4007.18 ms filled 16K, 8784.57 ms filled 32K).
Run IDs per point
All 13 publishable points are public records, each listed on /v1/run-sources with source llm-speed. Verified 2026-11-16 on GET https://api.llm-speed.com/v1/results/<id>: each record shows source llm-speed and CLI 0.0.23. Received times are Asia/Singapore (UTC+8).
- Short (p1024 preset, 991 actual tokens): 1 stream r_iqcsaltiygj (14:25:38), 2 streams r_w1ghhizti-d (14:25:51), 4 streams r_1xnjfp4smsq (14:26:07), 8 streams r_gihyz5jfgc8 (14:26:23), 16 streams r_4nge7d__8-x (14:26:44), 32 streams r_i1r0ngxz4hh (14:27:15).
- Filled 16K: 1 stream r_a9_1mrekhnd (14:27:32), 2 streams r_3ogoh9fqwyn (14:27:53), 4 streams r_-93wbtb83mc (14:28:25), 8 streams r_hwqgx8_47vr (14:29:14).
- Filled 32K: 1 stream r_vizpaqn9m8c (14:29:52), 2 streams r_dzvdfwvwcbr (14:30:24), 4 streams r_7nl1vae_gek (14:31:16).
All received 2026-11-12.
How the session was checked
- Runner:
run_qwen38_5090_sweep.final.py, sha256e25dfe60f8e489316be898c8bbd64f71c6bbd672061626c7a7fab87846028a99(e25dfe60). Security Desk SIGNED OFF this file (PASS) on 2026-11-12. After reviewing the session logs, Security Desk ACCEPTED the session on 2026-11-16; no repeat is needed. - Banner: the session log prints
RUNNER STAGING-run_qwen38_5090_sweep.v5b.py v5b(log line 3). That string is hard-coded in the final runner, so it is consistent with e25dfe60 having run. The session log does not itself print the runner hash. - All 13 valid ok runs were uploaded during the session with
--strict-anon; the bench printed each/r/link in the session log. - Only valid ok points with a matching BATCH_OK and finite metrics count as numbers. A NaN, inf or boolean in a numeric field makes a point invalid.
Third-party figures (@satellitedown / Cinference)
Reported by a third party. Not measured by llm-speed.
A separate block. These are @satellitedown's own reported figures, not our measurement. They are on the author's Cinference engine (not llama.cpp), a different engine, model build and setup. This post is not a reproduction of the Cinference demo. These figures are not compared with, combined with, or charted against the tables above.
- 1,623 tok/s peak-second combined.
- 1,099 tok/s decode.
- End-to-end: the source line records
end_to_end_tok_s 989.3and, on the next line,tokens_and_wall 14559 tok in 14.70s. 14559 ÷ 14.70 = 990.408…, which is 990.4 tok/s to one decimal. The stated end-to-end figure is 989.3; the tokens-and-wall fields in the same source recompute to 990.4. Both are quoted here; neither is used in our tables or chart. - Engine: Cinference (not llama.cpp); lanes reported: 8.
- Source: @satellitedown on X, posted 2026-11-12 01:49 SGT.
Related
Qwen3.8-27B model page · Why Qwen3.8-27B tok/s claims differ · RTX 5090 · decode vs prefill tok/s · methodology