Flint 40B-A2.5B
40 workload results across 6 hardware configurations.
Fastest config measured by llm-speed (@llmspeed)
179.4 decode tok/s
on RTX 4090 (24GB) via llama.cpp. see full run
For a standard UD-Q3_K_XL quantization using llama.cpp, here are measured results for short-chat generation.
On llama.cpp UD-Q3_K_XL, Flint-40B-A2.5B (16K context) is fastest on the RTX 4090 at 169.2 tok/s, 31% faster than the RTX 3090 (128.9 tok/s).
| Card | Decode tok/s | TTFT incl. reasoning tokens (98-token prompt) | Run | Source |
|---|---|---|---|---|
| RTX 4090 | 169.2 (single run) | 222 ms | r_sw92j6kg7js | llm-speed (@llmspeed) |
| RTX 3090 | 128.9 (single run) | 264 ms | r_v-sdiljpm7i | llm-speed (@llmspeed) |
Flint-40B-A2.5B (16K context), UD-Q3_K_XL, llama.cpp, chat-short, batch 1. Only cards with their standard memory are listed; CPU-only hosts are excluded. Community-submitted runs are signed on the submitter's own machine and are not measured by llm-speed; llm-speed verdicts use only its own runs.
Flint 40B-A2.5B vs Qwen3.8-27B on the same card and build
Measured by llm-speed (@llmspeed).
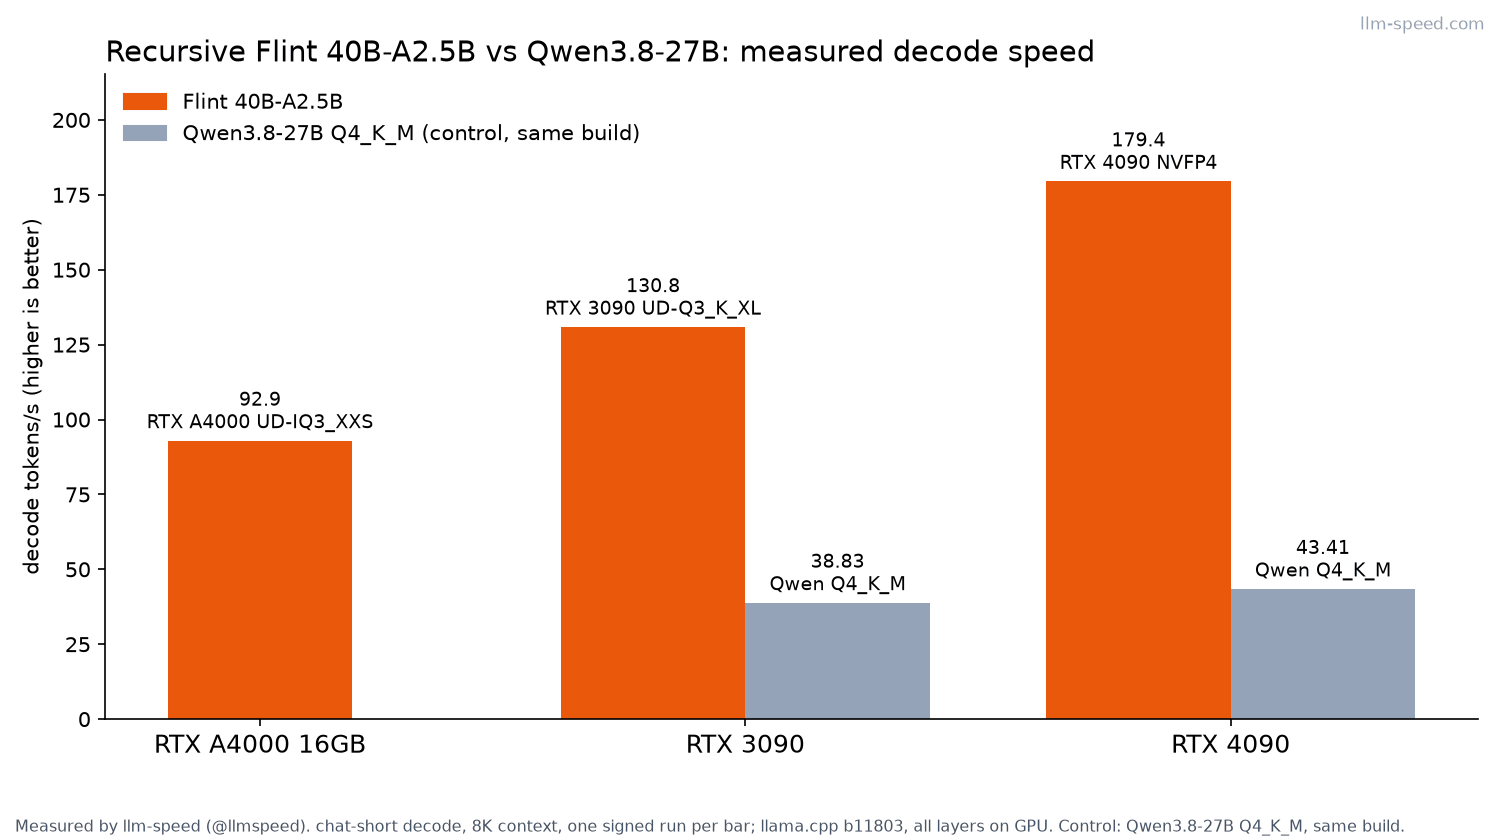
| Card | Flint 40B-A2.5B (8K) | Qwen3.8-27B Q4_K_M (8K) | Flint / Qwen |
|---|---|---|---|
| RTX 4090 | 179.4 tok/s NVFP4 (r_0i0a9uq6fdx) | 43.41 tok/s (r_k1hhpa9io2o) | 4.13× |
| RTX 3090 | 130.8 tok/s UD-Q3_K_XL (r_-yeg4qnhjp7) | 38.83 tok/s (r_w40_vv7f77w) | 3.37× |
| RTX A4000 16GB | 92.9 tok/s UD-IQ3_XXS (r_e8r7fxw1ke9) | no control run | — |
On the 4090, Flint's UD-Q3_K_XL (168.0 tok/s, r_r7gzl4lmmdc) is 3.87× the control. Qwen decode doesn't change with context: at 4K and 16K chat-short, the RTX 4090 ran 43.38 / 43.38 tok/s (r_7cap38a021-, r_cthpfm82n1r) and the RTX 3090 38.61 / 38.57 tok/s (r_mmtzel_i367, r_gscy1f7ey_k).
Caveats
- The quants differ: Flint is NVFP4 / UD-Q3_K_XL / UD-IQ3_XXS, and Qwen is Q4_K_M. Each model runs at the quant that fits the card.
- Prompts tokenize differently: Qwen's chat-short prompt is 154 tokens, Flint's is 98. This affects time to first token and prefill only, not decode.
- The Qwen GGUF is
Qwen3.8-27B-Q4_K_M.gguffrom ggml-org/Qwen3.8-27B-GGUF at main, revision a316ea5 (unverified: it isn't in the benchmark logs). The RTX 5090 and Mac presets pin revision 0669b98, so later controls on those machines may not use the same file revision. - No A4000 control.
- Control and Flint ran on different machines. 4090 control: driver 595.91.07. 3090 control: driver 580.65.06 (CUDA 13.0). The Flint 3090 and 4090 runs had 595.91.07.
- One run per config, no repeats.
- The RTX 4090 has no FP4 hardware path, so its NVFP4 bar measures memory-bound speed for a ~4.5-bit file, not FP4 tensor cores. NVFP4 (22.86 GB file) fits on 24GB; UD-Q4_K_XL (25.05 GB) doesn't.
Measured runs (40 workload results)
All runs were measured by llm-speed (@llmspeed).
RTX 4090 (24GB)measured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | NVFP4 | 179.4tok/s | – | 232ms | r_0i0a9uq6fdx | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | NVFP4 | 167.2tok/s | 4,992.3tok/s | 604ms | r_0i0a9uq6fdx | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | NVFP4 | 176.1tok/s | no data | no data | r_0i0a9uq6fdx | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | NVFP4 | 168.5tok/s | 8,953.3tok/s | 214ms | r_0i0a9uq6fdx | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 169.2tok/s | – | 222ms | r_sw92j6kg7js | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 157.8tok/s | 5,779.1tok/s | 522ms | r_sw92j6kg7js | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 166.2tok/s | no data | no data | r_sw92j6kg7js | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 160.4tok/s | 10,368.2tok/s | 184ms | r_sw92j6kg7js | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 168.0tok/s | – | 201ms | r_r7gzl4lmmdc | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 157.6tok/s | 5,789.2tok/s | 521ms | r_r7gzl4lmmdc | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 166.5tok/s | no data | no data | r_r7gzl4lmmdc | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 160.3tok/s | 10,408.2tok/s | 184ms | r_r7gzl4lmmdc | Measured by llm-speed@llmspeed |
RTX 4090 (24GB) + AMD EPYC 7452 32-Core Processor (32c) + 504GBmeasured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 39.82tok/s | – | 356ms | r_wap61ewkpzm | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 40.72tok/s | 2,006.3tok/s | 1,502ms | r_wap61ewkpzm | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 42.70tok/s | no data | no data | r_wap61ewkpzm | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 41.41tok/s | 4,498.6tok/s | 494ms | r_wap61ewkpzm | Measured by llm-speed@llmspeed |
RTX A4000 (16GB) + AMD EPYC 7453 28-Core Processor (56c) + 504GBmeasured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context (with CPU offload) | 15.67tok/s | – | 516ms | r_acy-a8qic5j | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context (with CPU offload) | 10.01tok/s | 840.9tok/s | 3,584ms | r_acy-a8qic5j | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context (with CPU offload) | 10.08tok/s | no data | no data | r_acy-a8qic5j | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context (with CPU offload) | 10.04tok/s | 1,988.6tok/s | 1,028ms | r_acy-a8qic5j | Measured by llm-speed@llmspeed |
RTX 3090 (24GB) + AMD EPYC 7763 64-Core Processor (128c) + 1008GBmeasured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 16.84tok/s | – | 489ms | r_klxxsjjp2m- | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 17.38tok/s | 1,316.2tok/s | 2,290ms | r_klxxsjjp2m- | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 16.80tok/s | no data | no data | r_klxxsjjp2m- | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q4_K_XL · 8K context (with CPU offload) | 17.04tok/s | 2,973.7tok/s | 701ms | r_klxxsjjp2m- | Measured by llm-speed@llmspeed |
RTX A4000 (16GB)measured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 16K context | 89.44tok/s | – | 300ms | r_tp8imqk28q5 | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 16K context | 83.27tok/s | 1,365.6tok/s | 2,207ms | r_tp8imqk28q5 | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 16K context | 86.71tok/s | no data | no data | r_tp8imqk28q5 | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 16K context | 82.73tok/s | 3,066.9tok/s | 658ms | r_tp8imqk28q5 | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 8K context | 92.89tok/s | – | 295ms | r_e8r7fxw1ke9 | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 8K context | 86.67tok/s | 1,458.7tok/s | 2,066ms | r_e8r7fxw1ke9 | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 8K context | 90.24tok/s | no data | no data | r_e8r7fxw1ke9 | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-IQ3_XXS · 8K context | 84.71tok/s | 3,147.3tok/s | 645ms | r_e8r7fxw1ke9 | Measured by llm-speed@llmspeed |
RTX 3090 (24GB)measured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 128.9tok/s | – | 264ms | r_v-sdiljpm7i | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 123.0tok/s | 2,739.8tok/s | 1,100ms | r_v-sdiljpm7i | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 128.7tok/s | no data | no data | r_v-sdiljpm7i | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 16K context | 124.4tok/s | 6,080.5tok/s | 330ms | r_v-sdiljpm7i | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 130.8tok/s | – | 268ms | r_-yeg4qnhjp7 | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 124.8tok/s | 2,824.8tok/s | 1,067ms | r_-yeg4qnhjp7 | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 130.2tok/s | no data | no data | r_-yeg4qnhjp7 | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | UD-Q3_K_XL · 8K context | 124.7tok/s | 6,225.9tok/s | 331ms | r_-yeg4qnhjp7 | Measured by llm-speed@llmspeed |
Can Flint 40B-A2.5B run on your hardware?
Fastest decode speed on each GPU or Mac, from llm-speed's own runs and community-submitted runs. Each page lists every quant and runtime and labels which runs llm-speed measured.
Flint 40B-A2.5B on hardware
GPUs compared on Flint 40B-A2.5B
Check it for your setup
- Predict your exact setup: estimate whether Flint 40B-A2.5B fits your GPU or Mac at your quant and context, next to measured speeds where we have them.
- Request this pair: ask for a measured Flint 40B-A2.5B run on hardware we have not measured. Requests are ranked by votes.
- Full run table (10 runs): every Flint 40B-A2.5B result we have, with links to each source run.