Sage-A1.5
28 workload results across 1 hardware configuration.
Fastest config measured by llm-speed (@llmspeed)
216.8 decode tok/s
on RTX 4090 (24GB) via llama.cpp (Q4_K_M). see full run
Sage-A1.5 on a 24GB RTX 4090: context vs memory
Measured by llm-speed (@llmspeed).
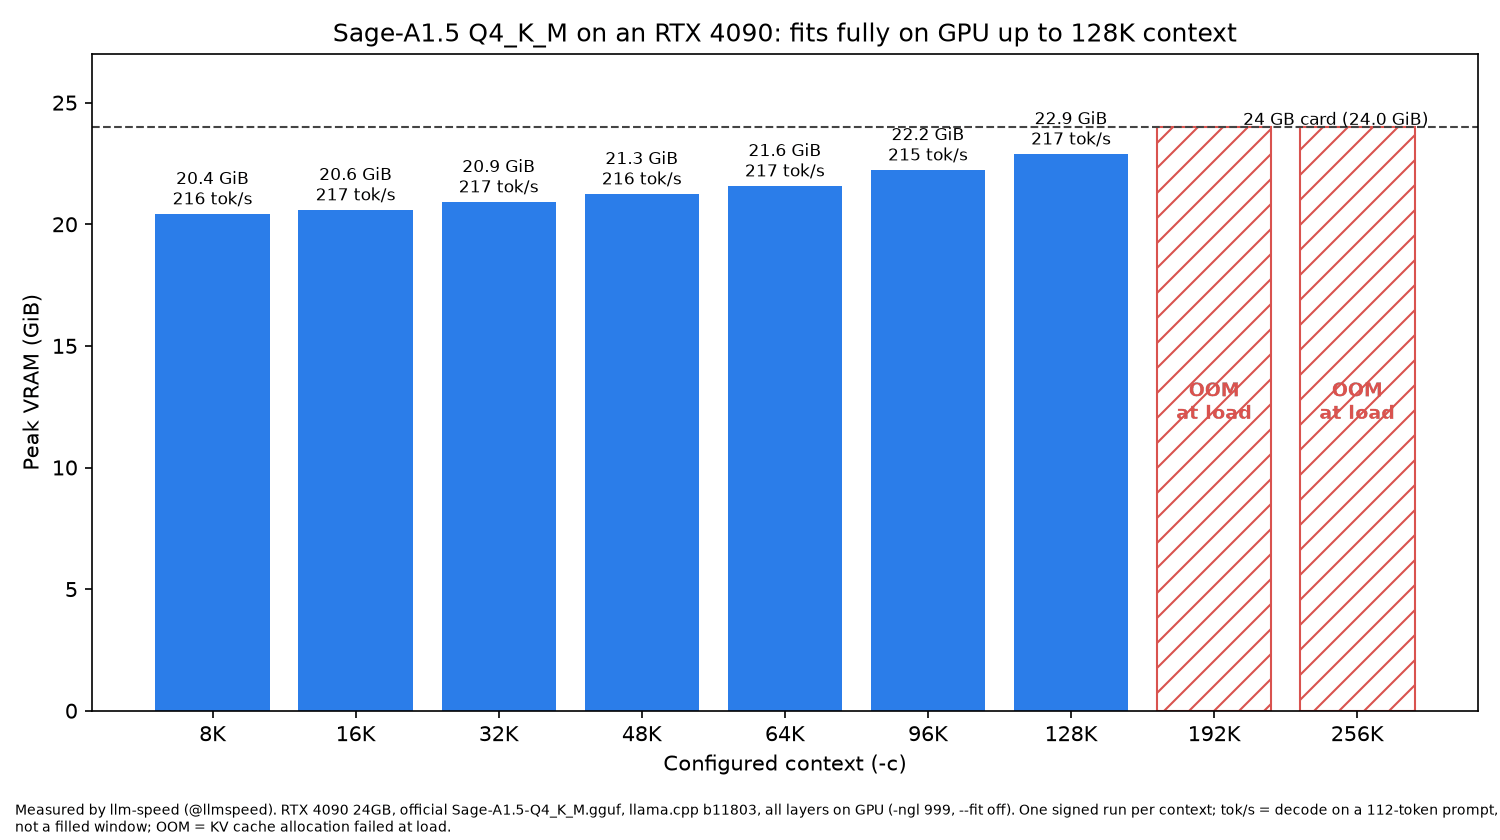
| Context | Peak VRAM (MiB) | Chat-short decode | Run |
|---|---|---|---|
| 8K | 20,928 | 216.5 tok/s | r_4x-4g-xhhgk |
| 16K | 21,096 | 216.6 tok/s | r_anosq1xr6tc |
| 32K | 21,432 | 216.8 tok/s | r_9uktwjj22y- |
| 48K | 21,768 | 216.3 tok/s | r_izwoxrsouc4 |
| 64K | 22,104 | 216.6 tok/s | r_vusd3gw5tpg |
| 96K | 22,776 | 215.3 tok/s | r_5nh2jxjbzur |
| 128K | 23,448 | 216.8 tok/s | r_-i4k-ieitrk |
| 192K / 256K | out of memory at load (KV cache allocation of 3,840 / 5,120 MiB failed) | ||
Caveats
- The sweep proves the memory fits: llama.cpp allocates the whole KV cache at load. Decode with the window actually filled to 128K was not measured.
- One run per context, no repeats. Text only: the 899 MB vision projector was not loaded, so 128K plus vision is not verified.
- Sage reasons before answering and had not started its answer within 256 output tokens, so the TTFT on this page is time to the first reasoning token, not to the answer.
- 16GB cards: the smallest official file (Q4_K_M) is 21.7 GB, so it does not fit; see Can an RTX A4000 run Sage-A1.5?
Measured runs (28 workload results)
All runs were measured by llm-speed (@llmspeed).
RTX 4090 (24GB)measured by llm-speed
| Workload | Backend | Quant | decode tok/s | prefill tok/s | TTFT incl. reasoning tokens | Run | Source |
|---|---|---|---|---|---|---|---|
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 128K context | 216.8tok/s | – | 109ms | r_-i4k-ieitrk | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 128K context | 212.0tok/s | 6,312.9tok/s | 504ms | r_-i4k-ieitrk | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 128K context | 216.4tok/s | no data | no data | r_-i4k-ieitrk | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 128K context | 208.0tok/s | 10,121.2tok/s | 201ms | r_-i4k-ieitrk | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 96K context | 215.3tok/s | – | 110ms | r_5nh2jxjbzur | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 96K context | 211.9tok/s | 6,300.5tok/s | 505ms | r_5nh2jxjbzur | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 96K context | 216.6tok/s | no data | no data | r_5nh2jxjbzur | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 96K context | 209.3tok/s | 10,163.9tok/s | 201ms | r_5nh2jxjbzur | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 64K context | 216.6tok/s | – | 107ms | r_vusd3gw5tpg | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 64K context | 212.4tok/s | 6,336.7tok/s | 502ms | r_vusd3gw5tpg | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 64K context | 216.5tok/s | no data | no data | r_vusd3gw5tpg | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 64K context | 210.4tok/s | 10,178.8tok/s | 201ms | r_vusd3gw5tpg | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 48K context | 216.3tok/s | – | 113ms | r_izwoxrsouc4 | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 48K context | 212.9tok/s | 6,267.7tok/s | 508ms | r_izwoxrsouc4 | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 48K context | 217.2tok/s | no data | no data | r_izwoxrsouc4 | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 48K context | 209.2tok/s | 10,163.1tok/s | 201ms | r_izwoxrsouc4 | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 32K context | 216.8tok/s | – | 109ms | r_9uktwjj22y- | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 32K context | 211.9tok/s | 6,341.3tok/s | 502ms | r_9uktwjj22y- | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 32K context | 215.4tok/s | no data | no data | r_9uktwjj22y- | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 32K context | 207.9tok/s | 10,174.9tok/s | 201ms | r_9uktwjj22y- | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 16K context | 216.6tok/s | – | 113ms | r_anosq1xr6tc | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 16K context | 211.6tok/s | 6,290.8tok/s | 506ms | r_anosq1xr6tc | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 16K context | 215.5tok/s | no data | no data | r_anosq1xr6tc | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 16K context | 207.9tok/s | 10,169.8tok/s | 203ms | r_anosq1xr6tc | Measured by llm-speed@llmspeed |
| chat-short | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 8K context | 216.5tok/s | – | 120ms | r_4x-4g-xhhgk | Measured by llm-speed@llmspeed |
| chat-long | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 8K context | 213.1tok/s | 6,342.5tok/s | 502ms | r_4x-4g-xhhgk | Measured by llm-speed@llmspeed |
| concurrent-decode | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 8K context | 216.9tok/s | no data | no data | r_4x-4g-xhhgk | Measured by llm-speed@llmspeed |
| agent-trace | llama.cpp@0.7.0-dev (build 11803, commit a37cc4610) | Q4_K_M · 8K context | 207.5tok/s | 10,214.9tok/s | 200ms | r_4x-4g-xhhgk | Measured by llm-speed@llmspeed |
Can Sage-A1.5 run on your hardware?
Fastest decode speed on each GPU or Mac, from llm-speed's own runs and community-submitted runs. Each page lists every quant and runtime and labels which runs llm-speed measured.
- RTX 4090 · 216.8 tok/s at 128K context
Sage-A1.5 on hardware
Check it for your setup
- Predict your exact setup: estimate whether Sage-A1.5 fits your GPU or Mac at your quant and context, next to measured speeds where we have them.
- Request this pair: ask for a measured Sage-A1.5 run on hardware we have not measured. Requests are ranked by votes.
- Full run table (7 runs): every Sage-A1.5 result we have, with links to each source run.