gemma3 on RTX 3090 (24GB) + AMD Ryzen Threadripper PRO 5975WX 32-Cores (32c) + 504GB
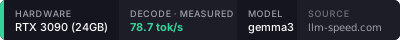
MeasuredOn 2026-10-16, gemma3 Q4_K_M ran at 78.7 tok/s (chat-short) on an RTX 3090 (24GB) with ollama. Run r_3gnxkzhhmyj.
RTX 3090 (24GB) + AMD Ryzen Threadripper PRO 5975WX 32-Cores (32c) + 504GB
suite suite-v1
cli 0.0.7
signed8P6X3/dgQr…
Embed badgesubmitted Oct 16, 2026Workload results
| Workload | Backend | Model | decode tok/s | prefill tok/s | TTFT | p50 | p95 |
|---|---|---|---|---|---|---|---|
| chat-short | ollama@0.31.1 | gemma3Q4_K_M | 78.65tok/s | 26.02tok/s | 4,534ms | 12.7ms | 12.9ms |
| chat-long | ollama@0.31.1 | gemma3Q4_K_M | 74.24tok/s | 1,648.1tok/s | 1,933ms | 13.5ms | 13.6ms |
| concurrent-decode | ollama@0.31.1 | gemma3Q4_K_M | 76.01tok/s | — | — | 13.1ms | 13.3ms |
| agent-trace | ollama@0.31.1 | gemma3Q4_K_M | 74.48tok/s | 2,887.7tok/s | 808ms | 13.4ms | 13.8ms |
Reproduce on your machine
Start with this model and workload selection. This command does not capture the original artifact, backend version or server settings:
Match quantization, context capacity, caching and runtime settings for a useful comparison. Duration varies by workload and hardware; the published client may differ from this run's version. How it's measured.
Share this run
Copy the short link, a Reddit-ready summary, or a README badge. Every number is the measured result on this page, and each badge links back to it.
https://llm-speed.com/r/r_3gnxkzhhmyjRelated benchmarks
- More gemma3 benchmarks — every backend and rig that has run this model.
- More RTX 3090 (24GB) LLM benchmarks — every model measured on this hardware.
Provenance
- Run ID
- r_3gnxkzhhmyj
- Fingerprint hash
- Public key
- 8P6X3/dgQrT7N3YkZfJIk4YG/PKBQUBlLR6aw2RXoG4=
- Received
- 2026-10-16 01:53:28