llama3.2 on RTX 5880 (48GB) + AMD EPYC 9T24 96-Core Processor (16c) + 62GB
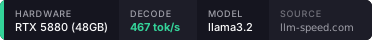
RTX 5880 (48GB) + AMD EPYC 9T24 96-Core Processor (16c) + 62GB
suite suite-v1
cli 0.0.6
signedbEJLrRXWo0…
Embed badgesubmitted Sep 19, 2026Workload results
| Workload | Backend | Model | decode tok/s | prefill tok/s | TTFT | p50 | p95 |
|---|---|---|---|---|---|---|---|
| chat-short | ollama@0.34.2 | llama3.2Q8_0 | 466.9tok/s | 44.32tok/s | 2,821ms | 2.1ms | 2.3ms |
| chat-long | ollama@0.34.2 | llama3.2Q8_0 | 441.9tok/s | 39,673.0tok/s | 79.4ms | 2.2ms | 2.4ms |
| concurrent-decode | ollama@0.34.2 | llama3.2Q8_0 | 464.2tok/s | — | — | 2.1ms | 2.2ms |
| agent-trace | ollama@0.34.2 | llama3.2Q8_0 | 452.3tok/s | 91,077.2tok/s | 21.8ms | 2.2ms | 2.4ms |
Reproduce on your machine
Start with this model and workload selection. This command does not capture the original artifact, backend version or server settings:
Match quantization, context capacity, caching and runtime settings for a useful comparison. Duration varies by workload and hardware; the published client may differ from this run's version. How it's measured.
Embed this run
Drop the badge into a README, blog post, or signature. Each render is a backlink to the signed result.
[](https://llm-speed.com/r/r_b948ehgi8g4)Related benchmarks
- More llama3.2 benchmarks — every backend and rig that has run this model.
- More RTX 5880 (48GB) LLM benchmarks — every model measured on this hardware.
Provenance
- Run ID
- r_b948ehgi8g4
- Fingerprint hash
- c8c55484fdad4e7a
- Public key
- bEJLrRXWo0ZHZvduikNM8kzBlCqoGiktMZ/PJgINFP8=
- Received
- 2026-09-19 17:48:43